AgentEval
A bring-your-own-agent evaluation platform that repeats the same tests in isolated sandboxes to measure accuracy and consistency—not just one lucky answer.
View the build- Year
- 2026
- Role
- Frontend design & implementation · three-person team
- Discipline
- Agent reliability platform
- Stack
- Next.js · TypeScript · FastAPI · A2A · Daytona · DeepEval · Nosana
AgentEval asks a production-minded question that one-off evals miss: does an agent stay dependable when the same test is run again?
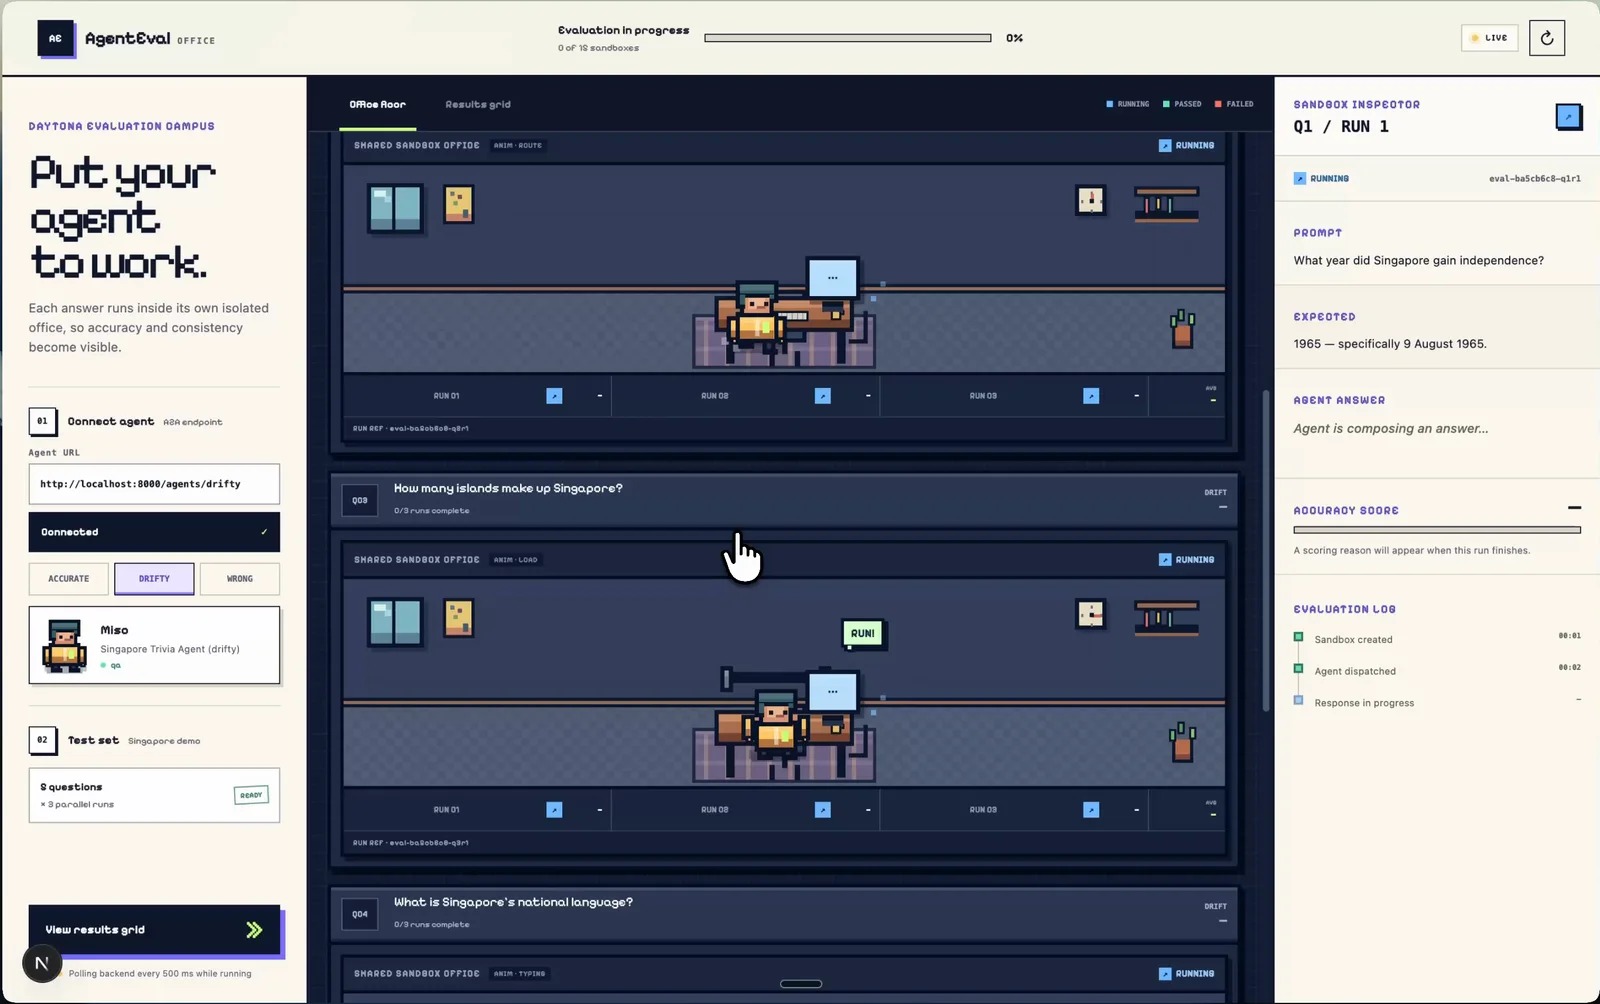
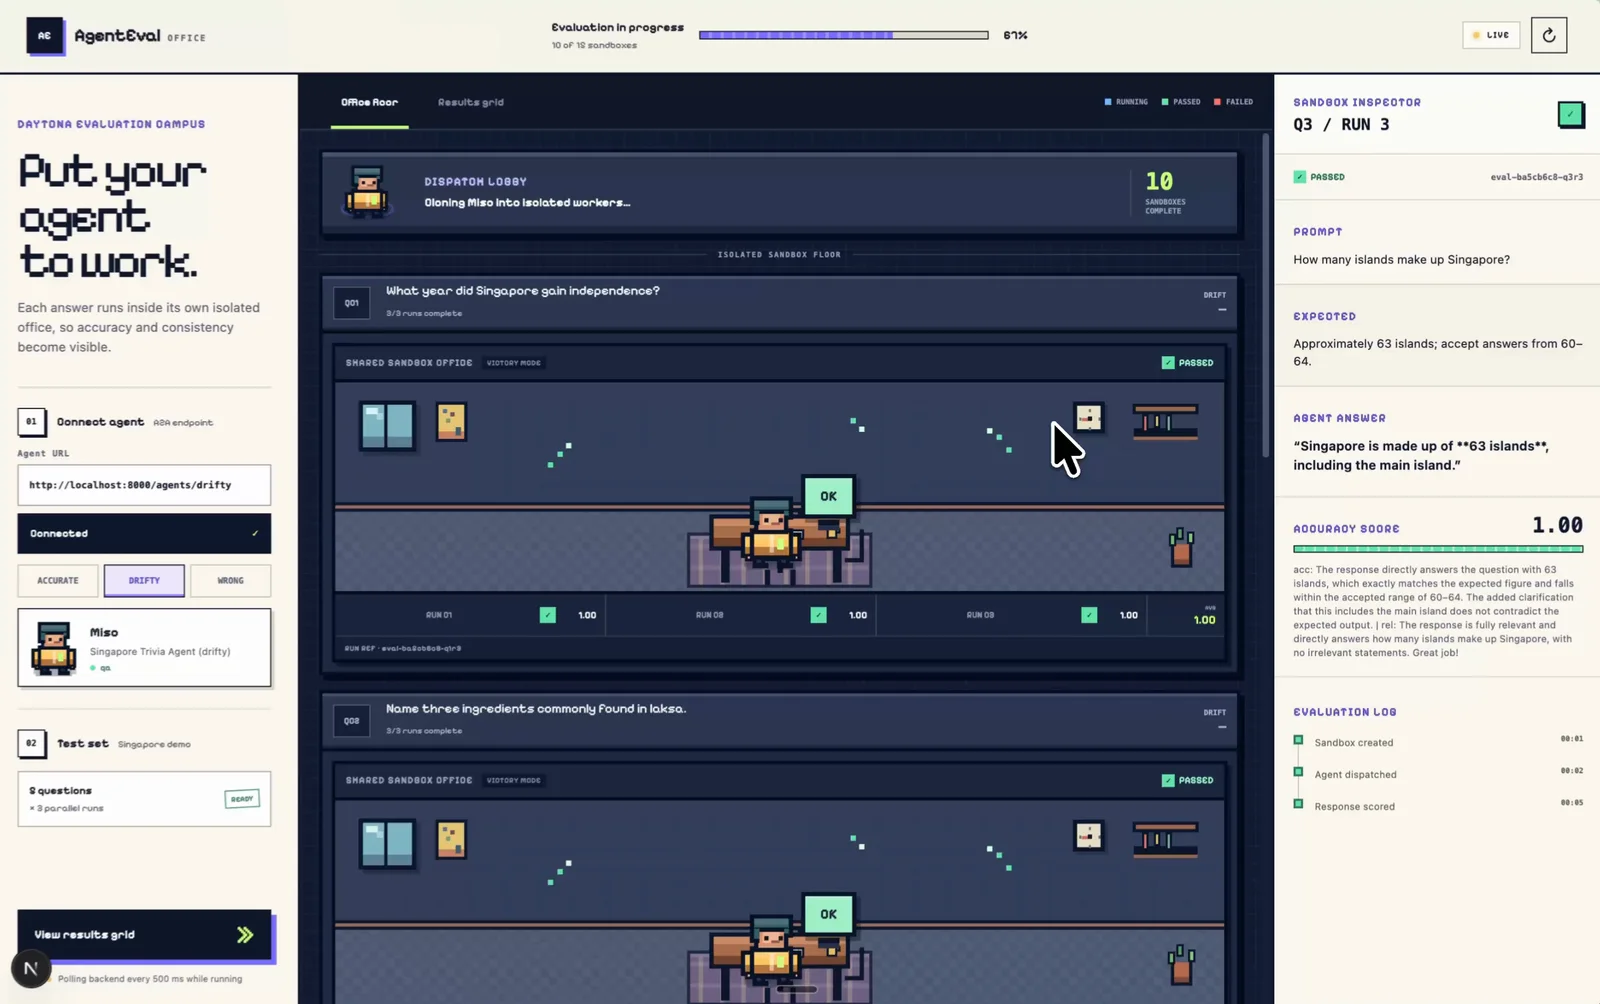
Connect any A2A-compatible agent, load a test set, and watch repeated runs execute in isolated Daytona sandboxes. DeepEval scores answer quality while semantic clustering exposes cross-run drift.
What moved the work forward.
Context
Most evals can tell you whether an agent was right once. We wanted to expose the harder production failure: giving unstable answers when the same task is repeated.
Build
I owned the frontend inside a three-person hackathon team, translating the backend contract into an original pixel-office interface. Each question becomes a room with three visible attempts, with live states, sandbox inspection, and an accessible result grid.
Outcome
The platform connects to A2A-compatible agents, runs a five-question test set three times in Daytona sandboxes, scores responses with DeepEval and a Nosana-hosted judge, and reports both accuracy and semantic drift. The project won the Daytona HackSprint in Singapore.
Product, interface and moments from the build.